Speech Data Built for Real Voices and Real Environments
Production-ready audio across languages, accents, speakers and acoustic conditions for ASR, conversational AI and speech intelligence.
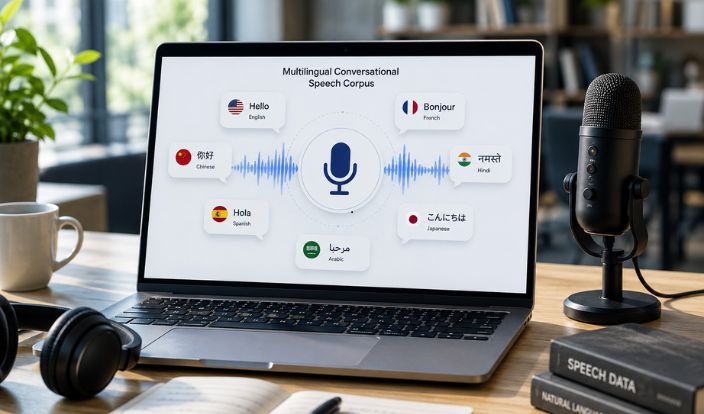
Multilingual & Diverse Speech
High-Quality Audio & Transcriptions
Built for Your Speech AI Use Case
Speech Datasets
Speech Datasets
Available Datasets
Sample-Ready datasets can be reviewed within days. Partner-Led collections are scoped around your language, speakers, acoustic environment, target application, and annotation requirements.
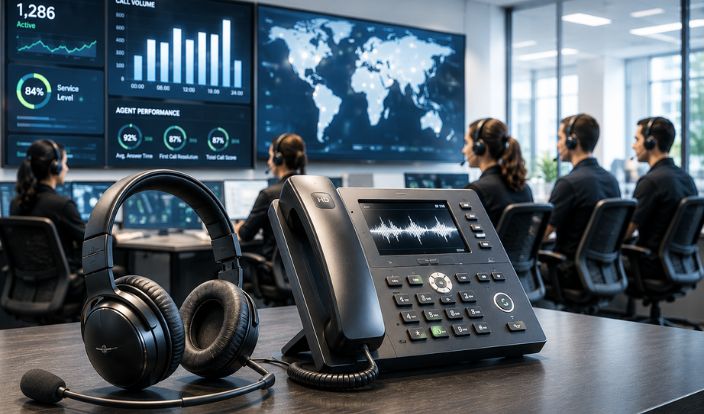
Call Center Dataset
Use Case: Real and Role based audio files
Format: WAV + JSON
Count: 50,000+ hours
*Volumes shown are indicative and can be scaled based on project requirements. Images are representative and may not reflect actual dataset samples. Request a sample to review the available dataset media.
Compliance
Compliance
Security & Compliance
HIPAA
ISO 9001 : 2015
SOC 2 Type ll
ISO 27001
GDPR
Accurate Data
Accurate Data
Why Choose Us?
Diverse, Real-World Speech Data
Capture natural speech across languages, accents, dialects, demographics, speaking styles, and real-world acoustic environments.
Built for Your Speech AI Use Case
Customize datasets by language, speaker profile, recording environment, audio quality, transcription format, and annotation requirements.
Privacy-First Data Collection
Speech data is collected and processed with appropriate consent, de-identification, and privacy safeguards for responsible AI development.
Human-Validated Transcriptions & Annotations
Expert-reviewed transcriptions and annotations help deliver accurate, consistent, model-ready speech data for training and evaluation.
Frequently Asked Questions
Frequently Asked Questions
Frequently Asked Questions
We provide speech datasets for ASR, conversational AI, voice assistants, speaker recognition, emotion detection, call-center intelligence, voice commands, multilingual applications, and speech understanding.
Yes. Datasets can be tailored by language, accent, dialect, speaker demographics, speaking style, recording environment, and target application.
Depending on the use case, annotations can include transcriptions, timestamps, speaker labels, language and accent tags, emotion labels, intent, sentiment, background noise, and other speech attributes.
Yes. Speech data is collected and processed with appropriate consent and privacy safeguards, including de-identification where required, to support responsible AI development.
Datasets can be delivered in common audio formats such as WAV and MP3, with specifications for sampling rate, bit depth, channels, noise conditions, and transcription or annotation formats based on your model requirements.